Ray Train: Diagnosing GPU Starvation in Model Training with Data Ingest Observability
Part 3 of our KubeRay series. This blog stands on its own, so you don't need the earlier posts to follow along. Part 2: KubeRay in production: best practices from the field covers how teams run KubeRay in production and how Anyscale KubeRay Connect fits on top of it.
The Anyscale platform has built-in observability for Ray workloads, and KubeRay Connect, introduced at the end of Part 2, brings it to the KubeRay clusters you already run. This post covers one of those features, built specifically for training workloads: Ray Train's data ingest observability.
LinkWhy GPU starvation is hard to catch
Model training is capital-intensive, so training teams need to pay close attention to GPU utilization. At the scale of hundreds or thousands of GPUs, even a small slowdown adds up to a lot of lost GPU-hours.
To keep GPUs busy, the next batch of data needs to be ready the moment the model finishes the current one. When it isn't, the GPUs sit and wait. That's GPU starvation, and it's one of the most common reasons utilization drops. It's also one of the quietest: nothing crashes, nothing alerts, and the job just keeps running a little slower than it should.
Teams usually notice one of two symptoms: GPU utilization that swings up and down instead of holding steady, or training runs that take longer than expected. In the run below, for example, SM activity on every GPU keeps rising and falling instead of reaching a plateau:
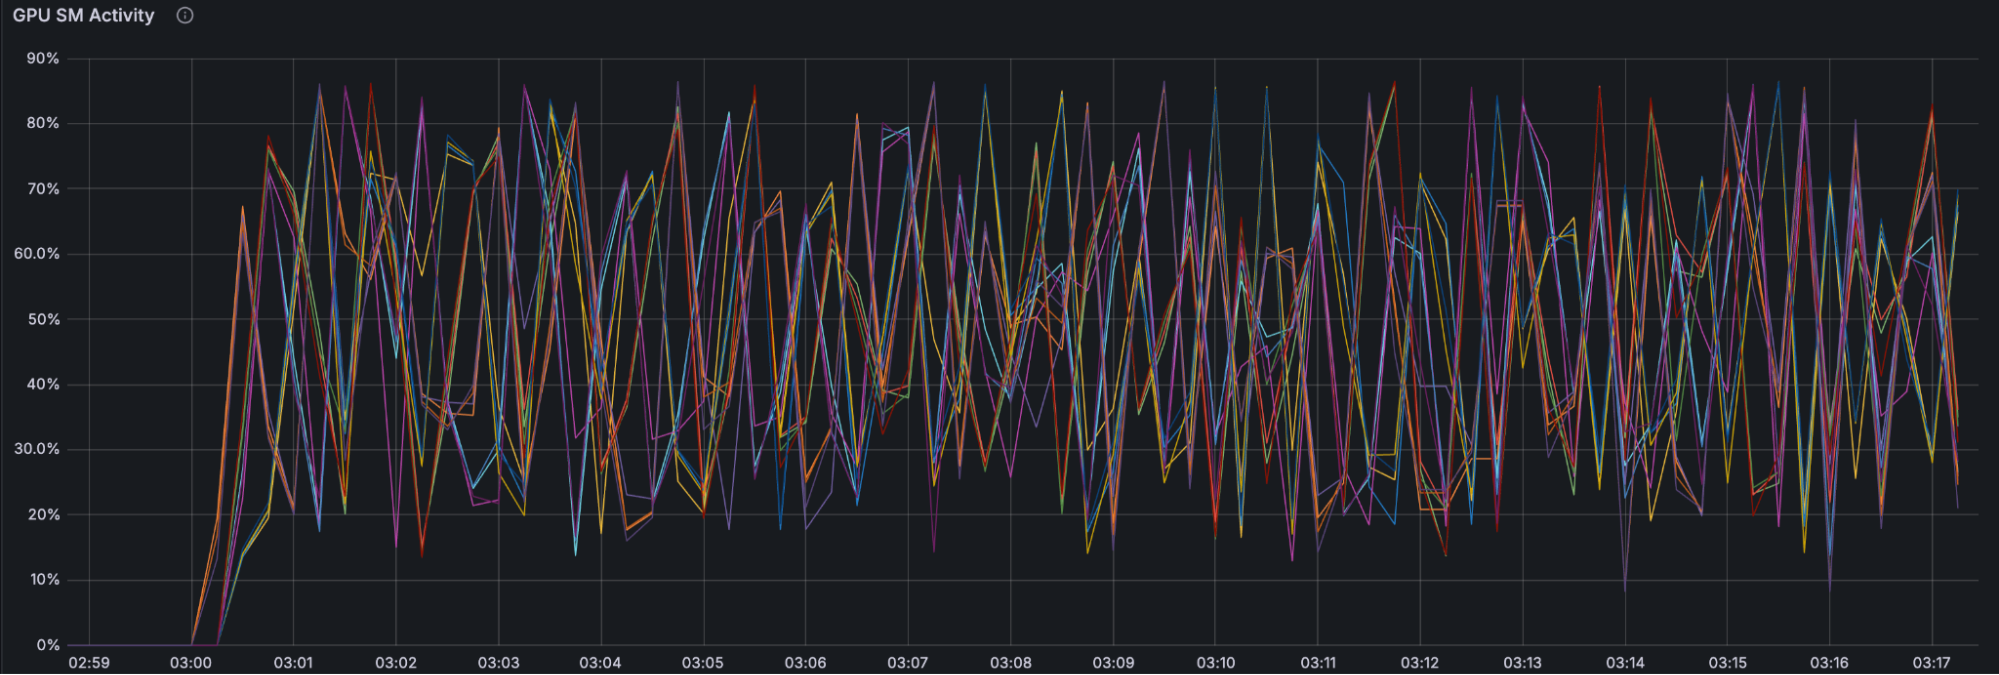
That pattern is a typical sign of GPU starvation. Data loading and training run in parallel: while the GPU trains on one batch, the next batch is being prepared. When preparing a batch takes longer than training on it, the training step finishes first and the GPU sits idle until the next batch arrives:
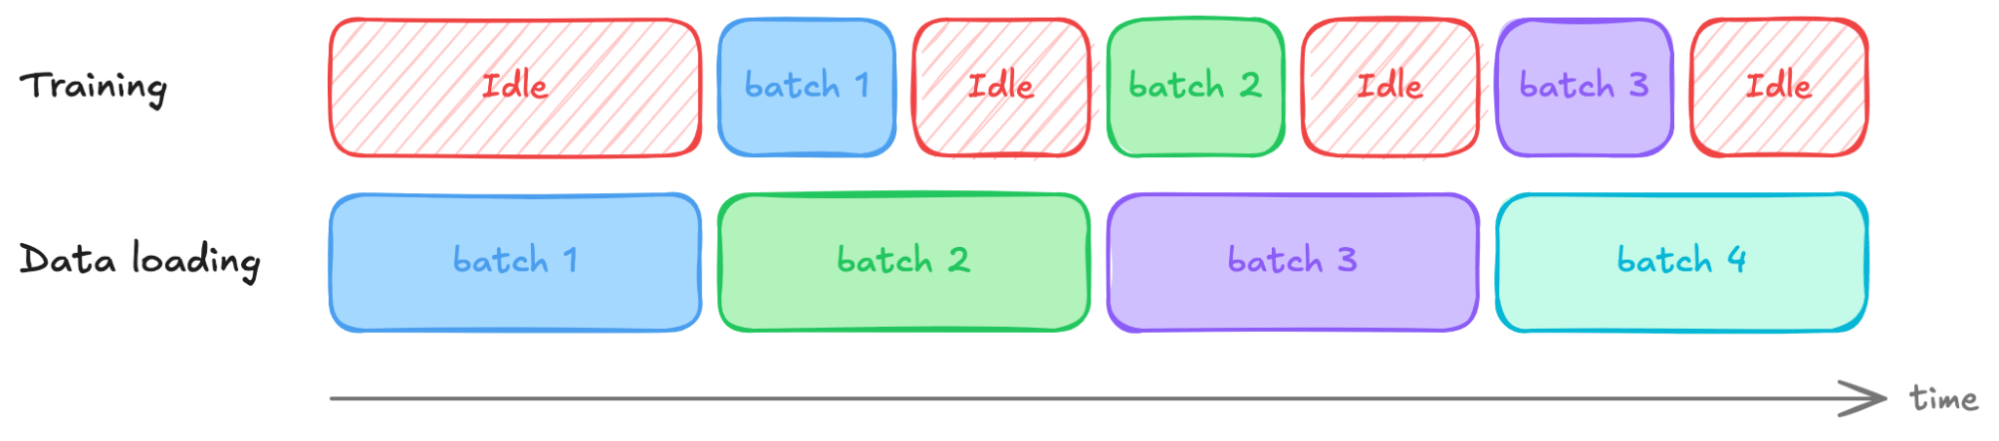
Each idle gap is one of the dips in the utilization graph above. The symptom is easy to spot. The cause is not. A batch can arrive late for a variety of reasons: a slow upstream data pipeline, data traveling over the network from another node, heavy preprocessing on the training worker such as an expensive collate_fn, or the host-to-device copy. Each cause has a different fix, so the first step is finding which stage is the bottleneck.
The rest of this post walks through the tools for doing that:
Data ingest metrics in open source Ray: how Ray Train and Ray Data time each stage of data loading, and how to read the Grafana graphs to see whether training is stalling on data, which stage is responsible, and what to change.
Data ingest observability on Anyscale: the same graphs with no setup, plus a live data ingest panel on the Ray Train dashboard that summarizes ingest health for every running dataset. KubeRay Connect brings both to KubeRay clusters you manage yourself.
LinkData ingest metrics in open source Ray
Starting in Ray 2.58, Ray Train and Ray Data record how long each batch spends in every stage of data loading, so you can see which stage is holding training back. If your Ray Train code already reads from Ray Data, no code changes are needed.
A typical setup looks like this. The driver defines a Ray Dataset, here Parquet files read from S3, and passes it to the trainer. Ray Train gives each of the eight training workers its own shard of the dataset. Each worker reads its shard with iter_torch_batches, which applies your collate_fn and returns batches of 64 rows as PyTorch tensors:
import ray
import ray.train
from ray.train import ScalingConfig
from ray.train.torch import TorchTrainer

train_ds = ray.data.read_parquet("s3://my-bucket/train/")

def train_func():
    shard = ray.train.get_dataset_shard("train")
    for batch in shard.iter_torch_batches(batch_size=64, collate_fn=my_collate):
        ...  # your training step

trainer = TorchTrainer(
    train_func,
    datasets={"train": train_ds},
    scaling_config=ScalingConfig(num_workers=8, use_gpu=True),
)
trainer.fit()
That single iter_torch_batches call is where all of the data loading happens. Like every other Ray Data iterator, including iter_batches, iter_rows, and to_tf, it moves each batch through the same pipeline before handing it to your training loop.
Inside that call, each batch passes through six stages on its way from the Ray Data pipeline to your GPU. Any of them can be the bottleneck:
Stage | What it measures |
|---|---|
Production wait | Waiting for the upstream Ray Data pipeline to produce the next block |
Data transfer | Fetching blocks to the training worker, including from another node's object store |
Batching | Slicing and combining blocks into batches, including any local shuffle buffer |
Format | Converting each batch to the requested format, such as NumPy or pandas |
Collate | Running your own per-batch preprocessing on the training worker, such as tokenizing text or padding sequences to a common length, passed in as |
Finalize | Copying the batch to the GPU (host-to-device transfer) in |
These stages don't run one after another on your training thread. Instead, a pool of background threads runs them concurrently to prepare the next batch while your training step runs. As long as the next batch is ready before your training step finishes, all of this work is hidden and doesn’t cost you any wall-clock time. When the next batch isn't ready in time, the training loop waits and the GPU sits idle. That wait is the exposed data loading time. Ray records it on every training worker, along with the time spent in each stage.
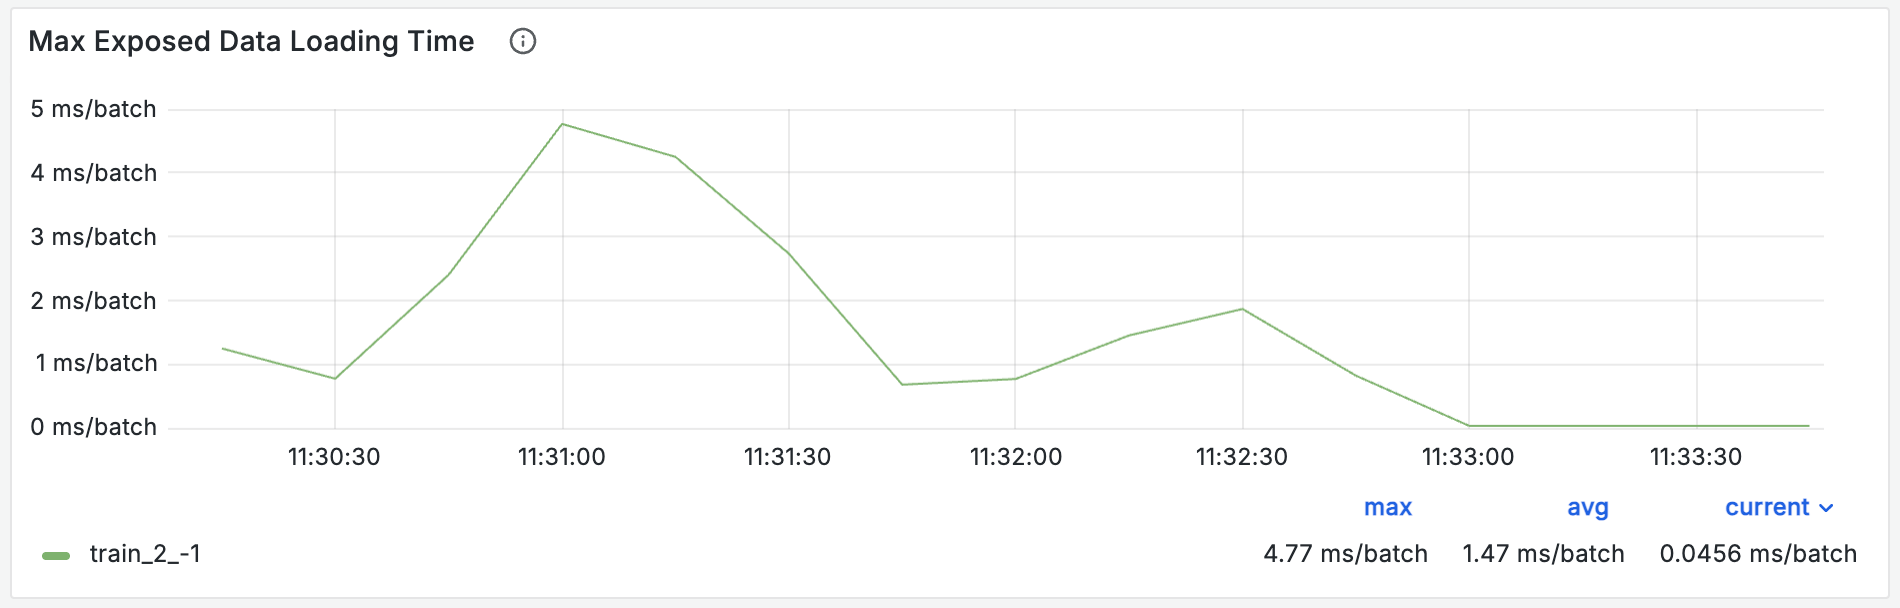
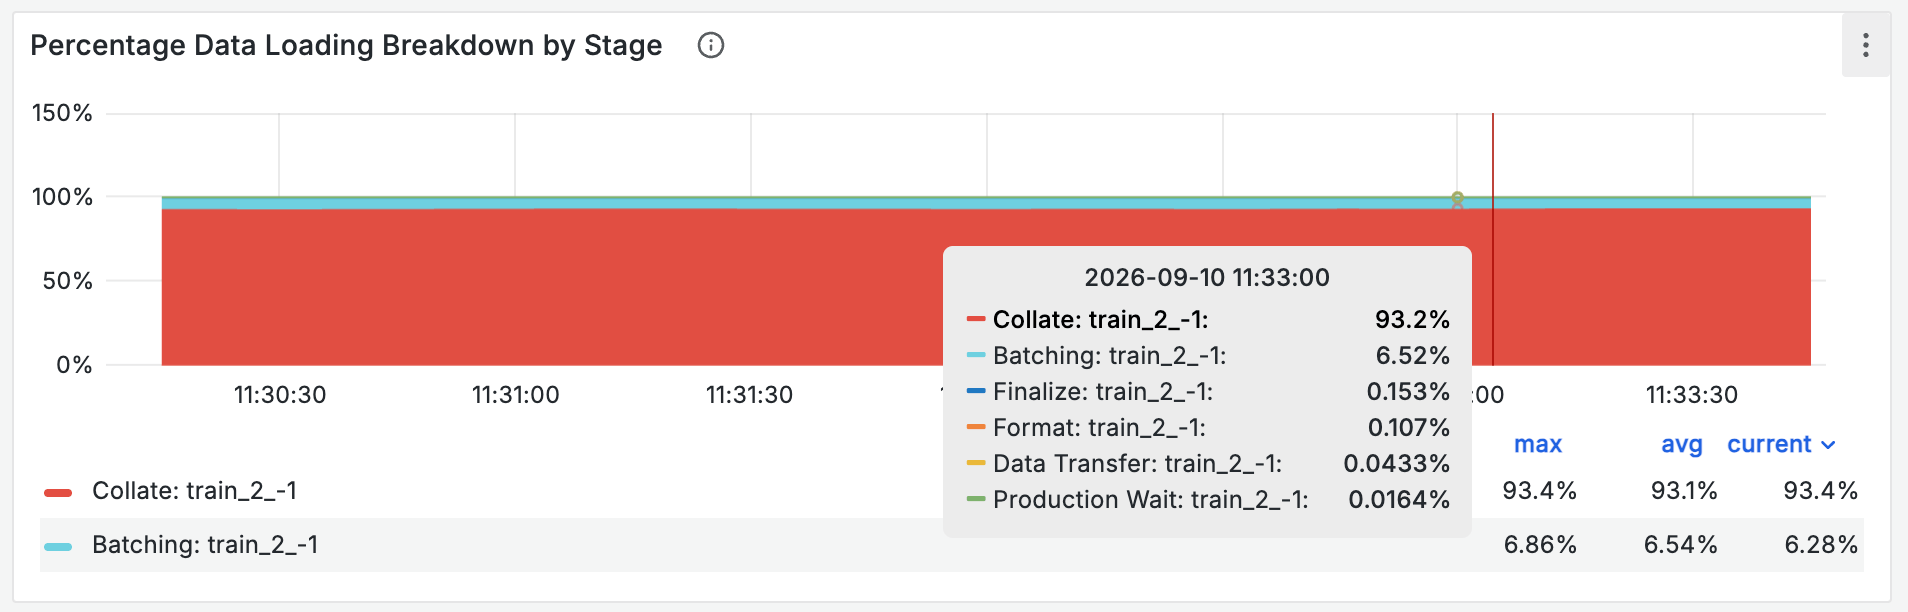
In open source Ray, these metrics appear in the Data Ingestion section of the Train Dashboard in Grafana once you set up Prometheus and Grafana for your cluster. The graphs answer three questions in order, shown here for a run that's stalling on an expensive collate_fn:
Is training stalling on data? Max Exposed Data Loading Time shows how long the training loop waits for each batch on the slowest rank. If it's zero, data loading keeps up, and tuning the pipeline won't help. If it isn't, that time is GPU idle time on every step.
Max Exposed Data Loading Time Which stage is responsible? Percentage Data Loading Breakdown by Stage shows each stage's share of data loading time, pooled across all ranks. A large production wait share means the upstream Ray Data pipeline can't produce data fast enough. A large share in any other stage points to work on the training worker itself.
Percentage Data Loading Breakdown by Stage Is it every rank or just one? Each stage has its own graph broken down by rank. If one rank sits well above the rest, it's a straggler, and because ranks synchronize on every step, a single slow rank can hold back the entire run.
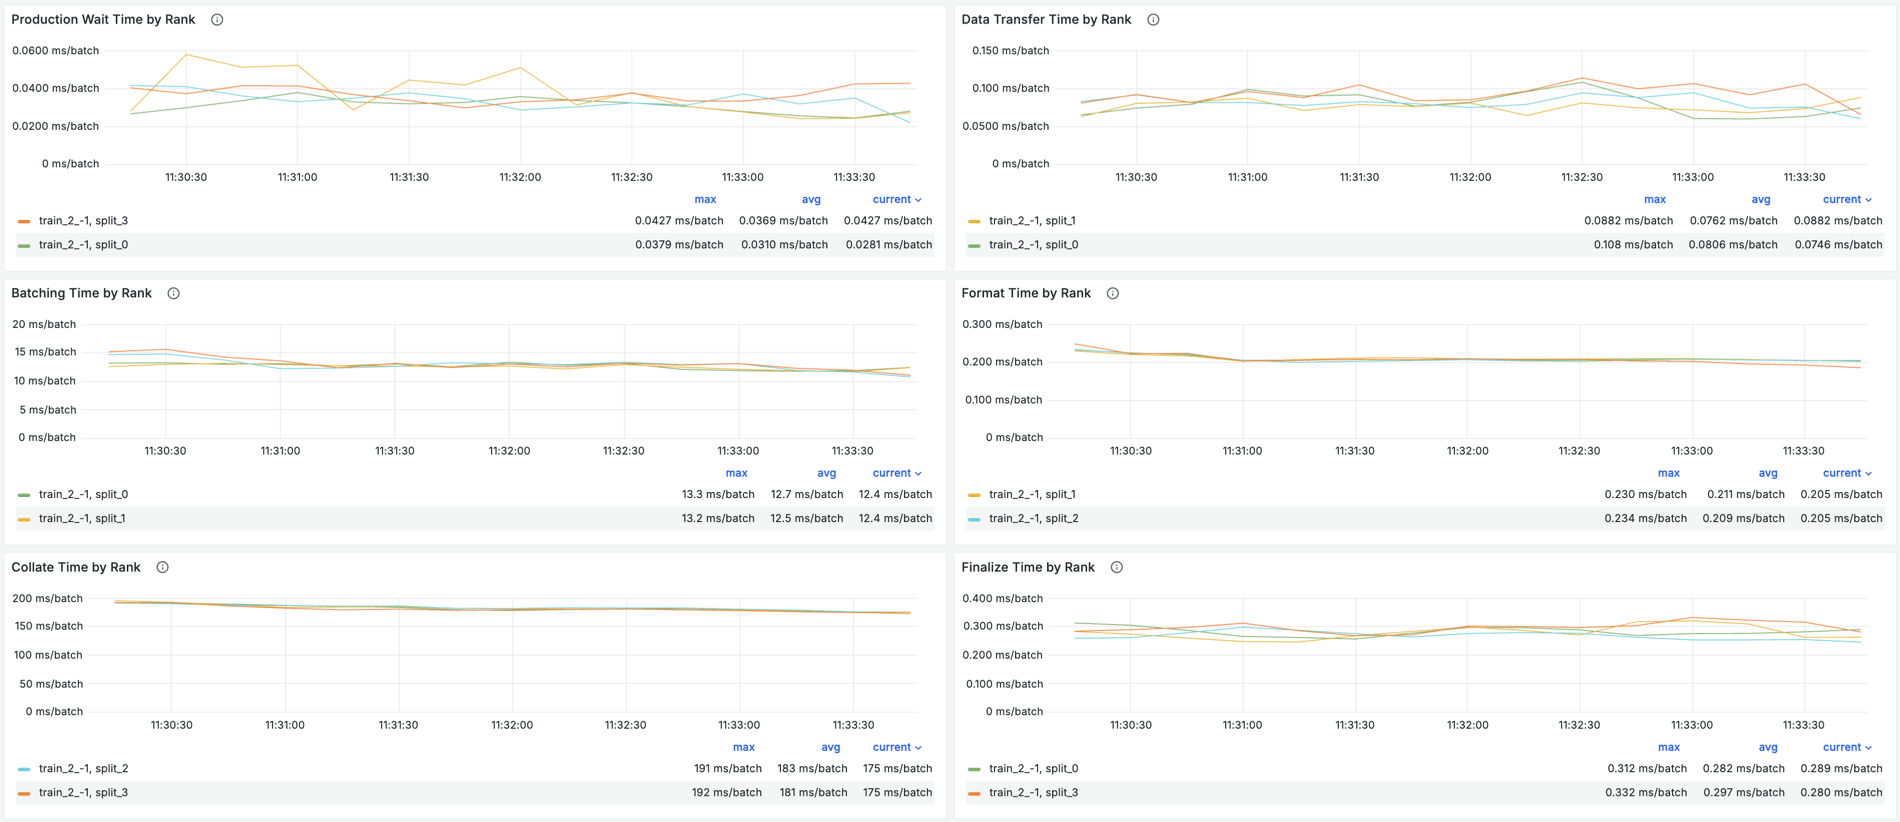
Production wait time by rank
Two throughput graphs round out the view. Data Ingest Throughput by Rank shows the rows per second each rank consumes, and Data Production Throughput shows the rows per second the Ray Data pipeline delivers to training. Together they show a healthy run's steady-state rate, so drops and imbalance across ranks stand out.
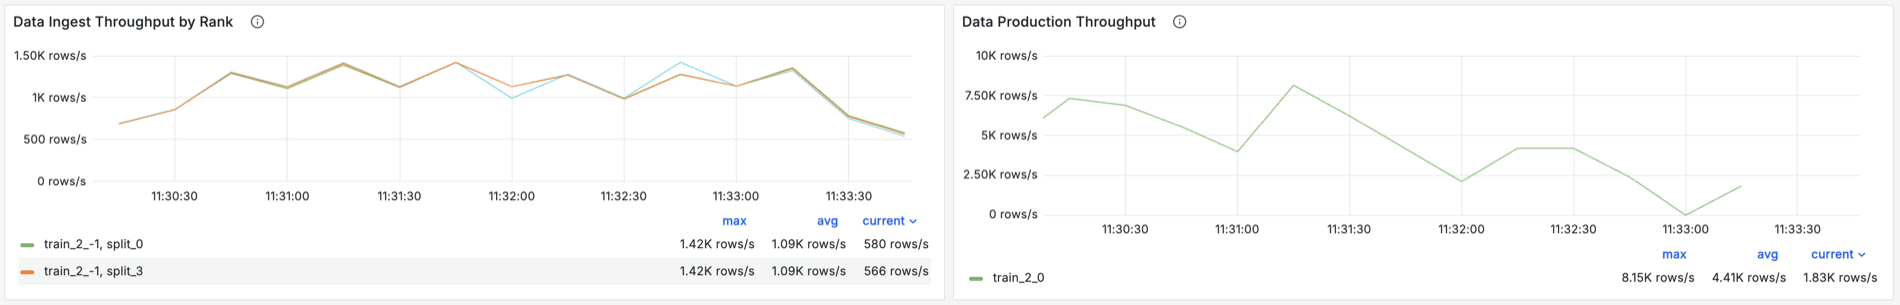
Knowing which stage is responsible is what makes the problem actionable, because each one points to specific things to check or change:
Bottleneck | What to try |
|---|---|
Production wait | Check the Ray Data dashboard for the slowest operator in your upstream pipeline and tune its configuration. You can also add CPU-only nodes so Ray Data can scale out preprocessing, or cache the preprocessed dataset in memory with |
Data transfer | Increase |
Batching | If you use |
Format | Increase |
Collate | Move heavy preprocessing out of |
One straggling rank | Check what's different about that rank's node. Common causes are Ray Data tasks competing with the training worker for CPU or memory, and blocks that are repeatedly fetched from remote nodes. If Ray Data tasks are competing for resources, keep them off the training nodes by pinning the dataset to CPU-only nodes with a |
LinkData ingest observability on Anyscale
On Anyscale, you get all of these Grafana graphs with no setup. Anyscale collects the metrics for every training run and shows the graphs on the Ray Train dashboard, so there's no Prometheus or Grafana to host.
On top of the Grafana graphs, the Ray Train dashboard on Anyscale includes a live data ingest panel. Instead of reading through a dozen graphs, you get one live view of data ingest health across your whole cluster. The sped-up recording below shows it on a run that's stalling on collate:
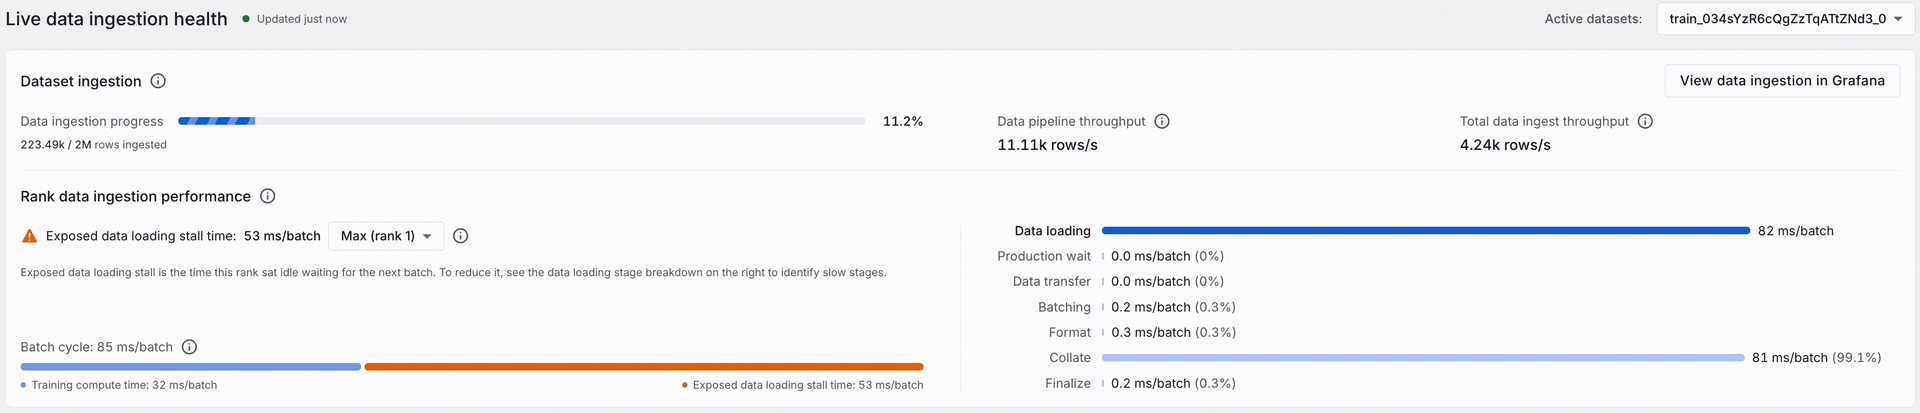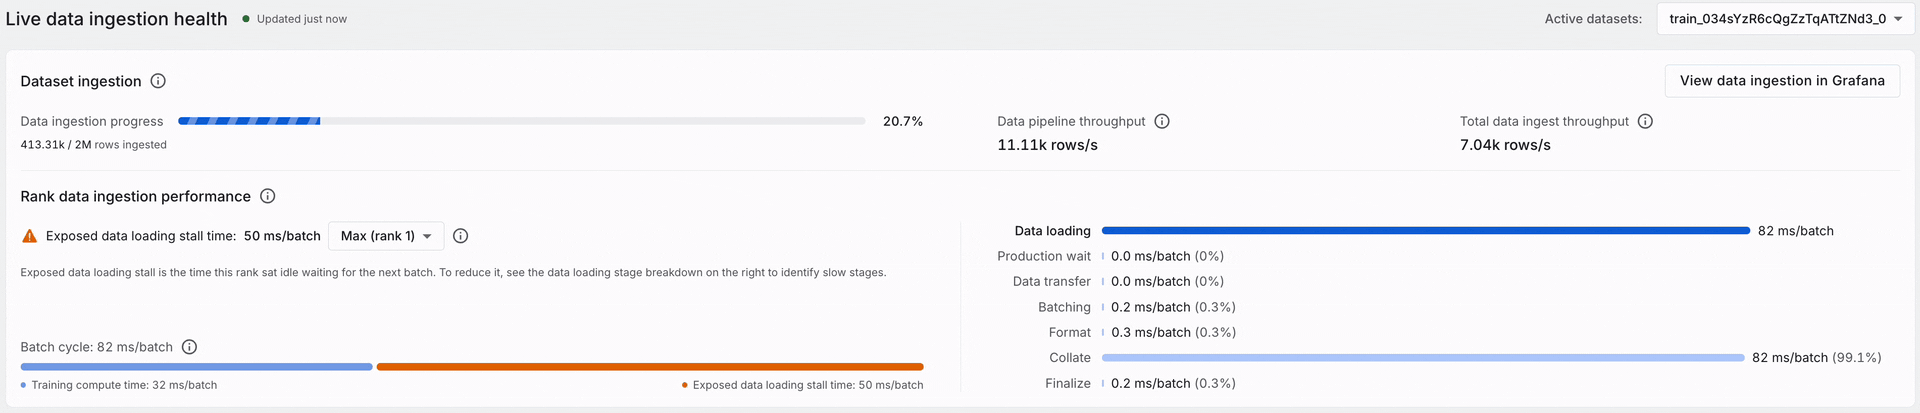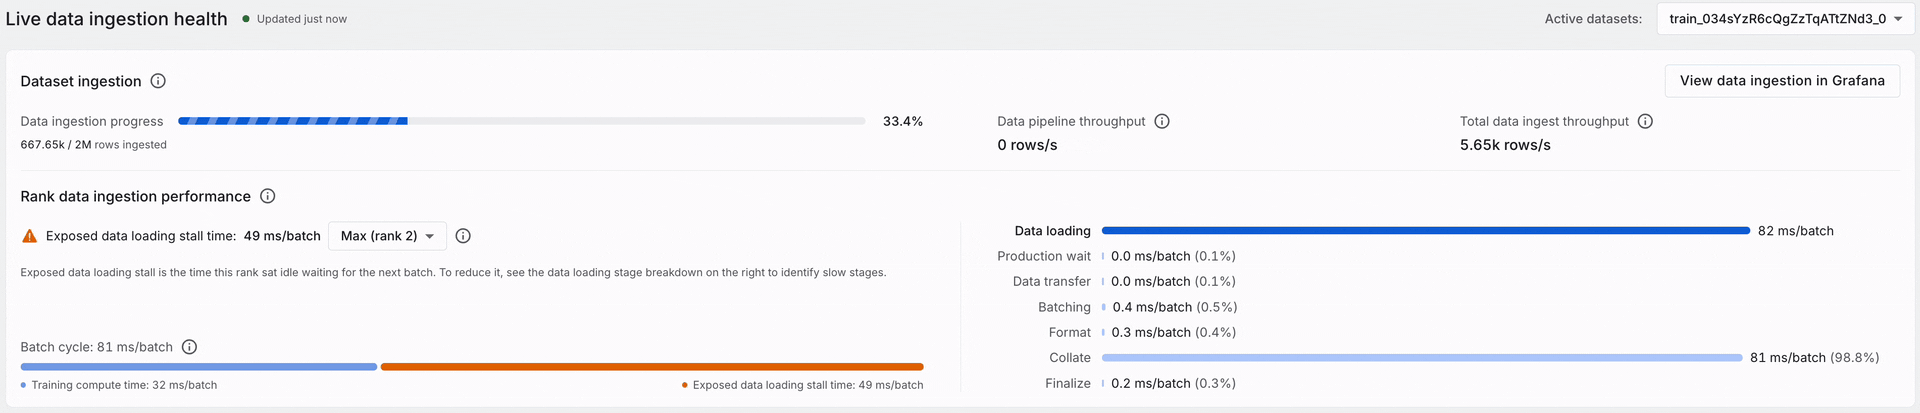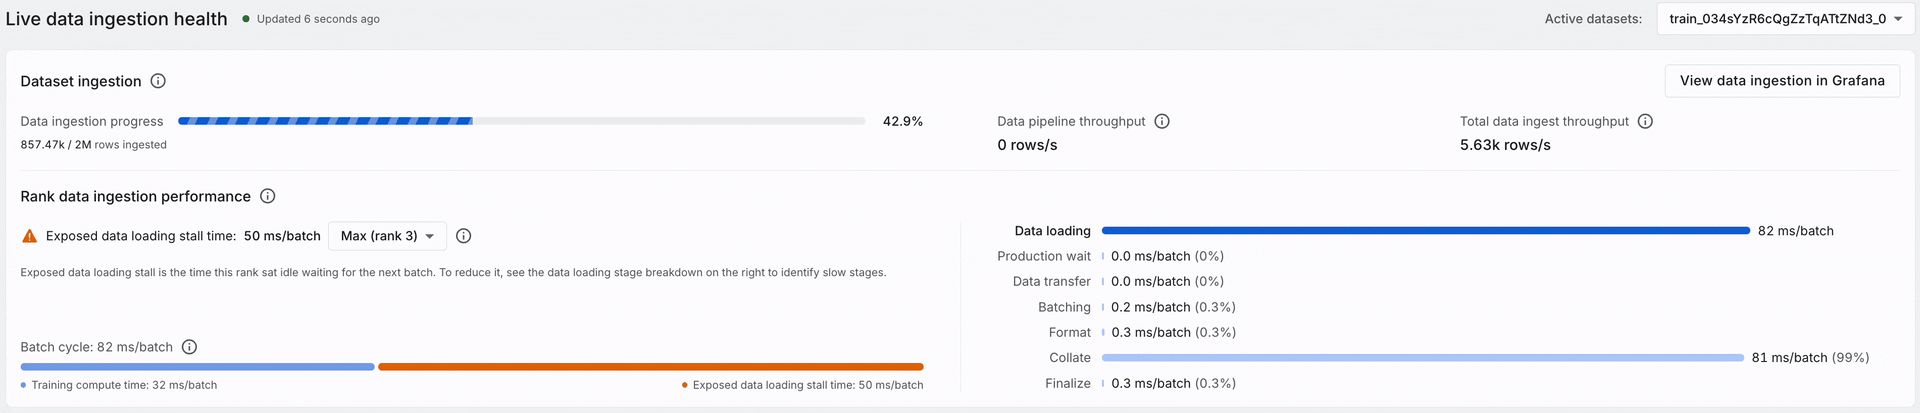
For each Ray Data dataset that's currently executing, the panel shows the following. Per-batch metrics are for the rank you select; the recording shows the slowest rank.
Ingestion progress: how far training has gotten through the dataset, as rows ingested out of the total.
Throughput: rows per second produced by the upstream data pipeline and ingested by training in total.
Exposed data loading stall: how long the training loop waits on data for each batch.
Training compute time: how long the training step takes for each batch.
Batch cycle: each batch's total time, split between training compute and the exposed stall.
Stage breakdown: time per batch in each of the six data loading stages, so the bottleneck stands out. In the recording, collate takes almost all of it, which points straight at the
collate_fn.Link to Grafana: one click to the full Data Ingestion graphs, for historical metrics and more detail.
Everything in this section is part of the observability built into the Anyscale platform. If you run your own KubeRay clusters, KubeRay Connect brings it to them without migrating workloads.
With these metrics, unstable GPU utilization becomes something you can trace to a single bottleneck, instead of something you guess at. Fix that stage and your GPUs stay fed: utilization rises and holds steady, and the same run finishes sooner on the same hardware.
To go deeper, see these guides in the Ray docs:
Debug data loading bottlenecks covers the full drill-down and the fix for each result.
How does Ray Data iterate over data? covers the threading model behind the six stages.
LinkSummary
Unstable GPU utilization tells you that something is wrong without telling you what. Starting in Ray 2.58, per-stage data loading metrics in Ray Train and Ray Data close that gap. They tell you whether data loading is what's holding training back and, if it is, where the bottleneck is, so you know where to look next. In open source Ray, the metrics show up in the Train Dashboard in Grafana. On Anyscale, you get the same graphs with no setup, plus a live data ingest panel that summarizes every running dataset.
LinkNext steps
GPU starvation is one of several issues that make production training hard to debug, and the Ray team is continuing to build observability into Ray Train for the most common ones. Here's what we're working on next:
Automatic hang detection and stack trace capture. Ray Train will detect when training stops making progress and automatically capture stack traces from every worker, so you can see where each one is stuck without reproducing the hang.
Health monitoring. More extensive monitoring of training health, including hardware health checks, to surface the problems that slow down or stop production training runs.
If you run into a data ingest issue these tools don't cover, or have ideas for what we should build next, file an issue on GitHub.